Ask an engineering team what a feature costs to run and you usually get a shrug and a gesture at the cloud bill. Ask the same question about an AI feature and the shrug is more expensive, because this time the answer scales with every single request.
Per-token pricing changed something structural about how software costs behave. In a conventional web application, serving a request twice as often costs a little more compute and nothing else; the marginal cost of a request rounds to zero. Under per-token pricing, the marginal cost is the cost. Every architectural decision you make — how much context you send, which model you send it to, how many times you retry, whether you cache — has a price attached, and that price gets multiplied by your traffic every month for as long as the feature exists.
That makes cost an architecture concern rather than a procurement one. You cannot negotiate your way out of a design that sends forty thousand tokens of context to a frontier model in order to answer a yes-or-no question.
Where the money actually goes
When I instrument a system for the first time, the spend almost always concentrates in four places, in roughly this order.
Input tokens, not output tokens. Teams tend to think about what the model writes, because that is the part they can see. But most production prompts are heavily front-loaded: a system prompt, a handful of few-shot examples, retrieved documents, conversation history, and then two lines of actual user input. Output is usually a few hundred tokens. Input is frequently thousands. Even accounting for output tokens being priced several times higher, input volume often dominates the bill.
Context that grew by accretion. Nobody designs a six-thousand-token prompt. It arrives one incident at a time: an example added to fix an edge case, a paragraph of instructions added after a bad output reached a customer, a retrieval step that returns the top ten chunks because someone once tried five and it missed something. Each addition is individually justifiable. Together they are most of your invoice.
Retries you are not counting. A malformed JSON response that triggers an automatic retry costs you the full prompt again. If five per cent of calls retry once, that is a five per cent surcharge on everything, and it does not appear anywhere in your dashboards unless you went looking for it.
Re-embedding the same content. Embedding pipelines that re-process unchanged documents on every run are quietly common, and unlike the other three, this one is almost always pure waste.
A worked example
Take a support-triage feature handling 50,000 requests a month. Each request sends about 4,000 input tokens and gets back about 500. Using illustrative rates of $3 per million input tokens and $15 per million output tokens for a large model:
Input:   50,000 x 4,000  =  200M tokens  x $3/M   =  $600
Output:  50,000 x   500  =   25M tokens  x $15/M  =  $375
                                            Monthly  =  $975
Now make two changes that have nothing to do with negotiating a discount.
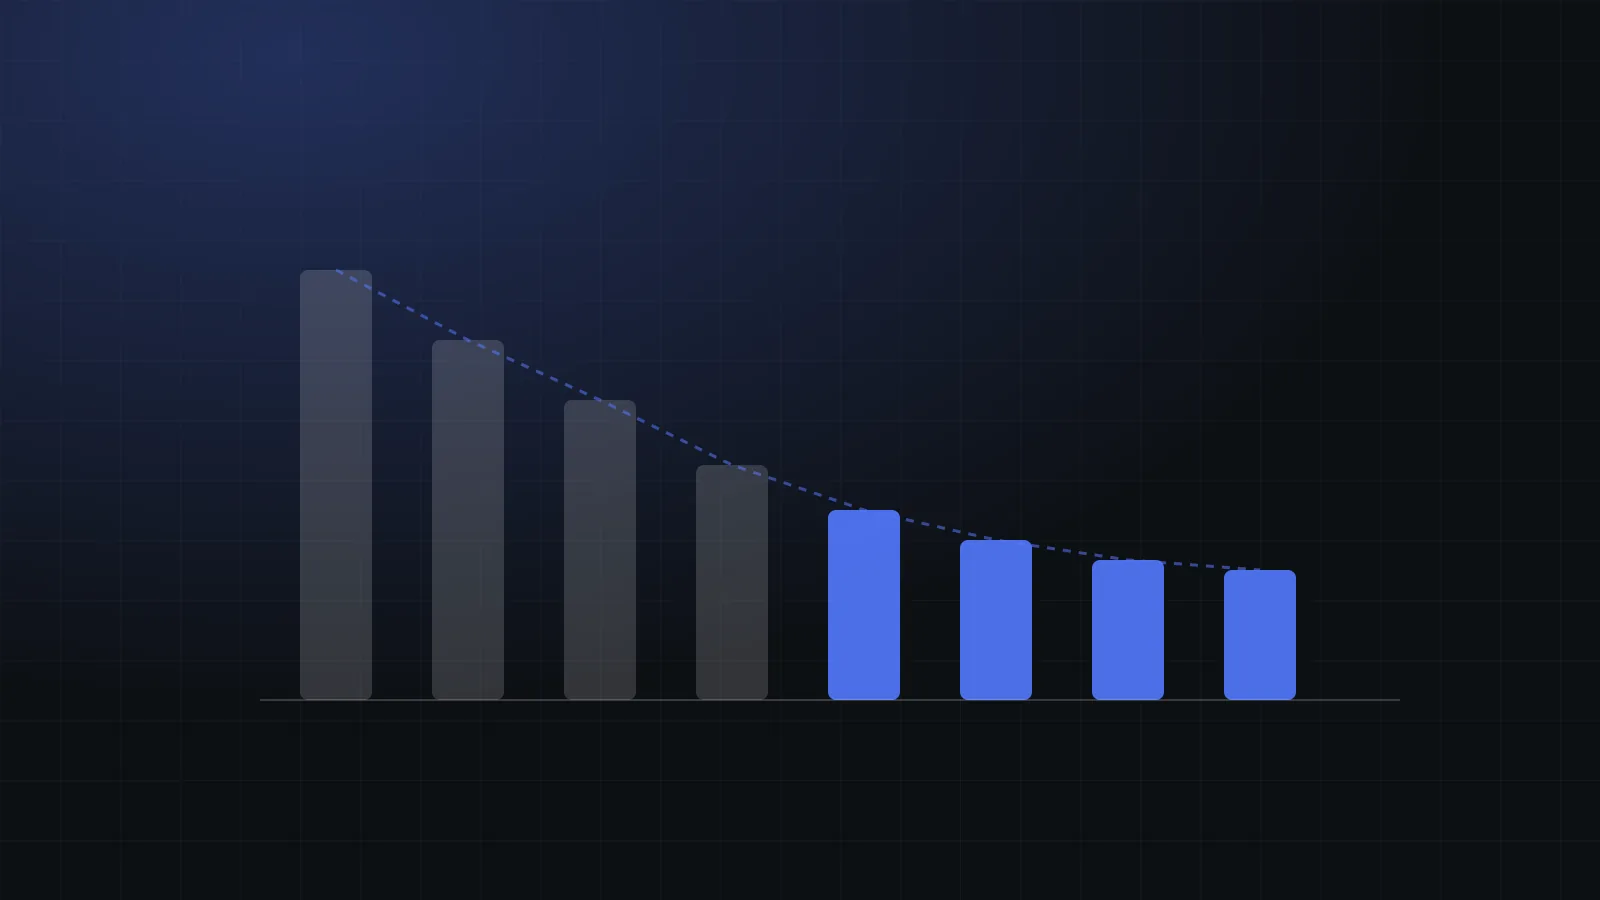
First, context discipline. Most of those 4,000 input tokens are retrieved chunks and few-shot examples that stopped earning their place months ago. Cutting the prompt to 1,200 tokens without measurable quality loss — a typical result once you actually test it — takes the input side from $600 to $180. The bill is now $555.
Second, routing. Classify each request and send the straightforward 70 per cent to a smaller model at, say, $0.25 per million input and $1.25 per million output, escalating the rest:
Small model (35,000 reqs):   42M in  x $0.25/M  =  $10.50
                             17.5M out x $1.25/M  =  $21.88
Large model (15,000 reqs):   18M in  x $3/M      =  $54.00
                              7.5M out x $15/M    =  $112.50
                                            Monthly  =  $198.88
From $975 to roughly $199 — a 79 per cent reduction — without changing providers, renegotiating anything, or degrading the answers that matter. Both changes are architecture. Neither is a procurement win.
The question is never “which model is cheapest?” It is “what is the smallest amount of the most expensive thing this request actually needs?”
Model the bill before you ship
The single highest-leverage habit I can recommend is embarrassingly simple: before a model-backed feature ships, write down its cost per request and multiply it by your projected volume. Not the pilot volume — the volume at the point where the feature is successful.
cost_per_request = (input_tokens  x input_rate)
                 + (output_tokens x output_rate)
                 x (1 + retry_rate)

monthly_cost     = cost_per_request
                 x requests_per_month
                 x (1 - cache_hit_rate)
Five minutes of arithmetic on the back of an envelope has killed more bad AI features in my experience than any amount of review process. It also reframes the conversation productively: when a product manager can see that an extra retrieval step costs $4,000 a year at expected volume, the discussion about whether it improves quality enough becomes much more concrete.
What to instrument
You cannot manage what you have not attributed. At minimum, log for every model call: the feature and call site, the model used, input and output token counts, whether it was a cache hit, whether it was a retry, and latency. That is six fields. It takes an afternoon to add and it changes every cost conversation you will have afterwards.
The dashboard that matters is not “spend by provider.” It is cost per feature per user action. Providers bill you by account; your business cares about unit economics. Those are different numbers, and only one of them tells you what to do next.
The uncomfortable part
Sometimes the honest conclusion from this exercise is that the feature does not work economically at any model price. A summarisation step that costs eleven cents per user action inside a product with a two-dollar monthly ARPU is not a cost optimization problem. It is a product decision wearing a cost optimization costume, and the earlier someone says so out loud, the cheaper it is to fix.
That is not an argument against building with models. It is an argument for knowing the number before you find out the hard way, six months in, when the feature is load-bearing and the bill has become someone’s quarterly problem.